Posts
500Following
100Followers
5141
 repeated

Josh Bressers
joshbressers@infosec.exchangeI'm not sure claiming "everything is on fire" is the correct takeaway here
There is a pile of flammable materials we've been ignoring for decades. It catches on fire sometimes. It caught on fire a lot this week
And the people who put out the fires, for free, put the fire out again
The current plan is to just keep throwing more oily rags on the pile. We could try to help the volunteers, but that costs more than adding oily rags to the pile
 7
15
 3
Greg K-H
gregkh
0
4
12
repeated

European Open Source Academy
europeanOSacademy@fosstodon.org⏳ 2 weeks left to nominate for the European Open Source Awards 2027!
The European Open Source Awards exist to make the quiet work visible, and to celebrate the individuals and communities advancing innovation, collaboration and digital sovereignty in Europe.
👉 Nominate by 1 November: https://awards.europeanopensource.academy/nomination-process
#EOSAwards #OpenSource #EuropeanOpenSourceAcademy
 0
3
0
Greg K-H
gregkh
0
0
0
repeated

VessOnSecurity
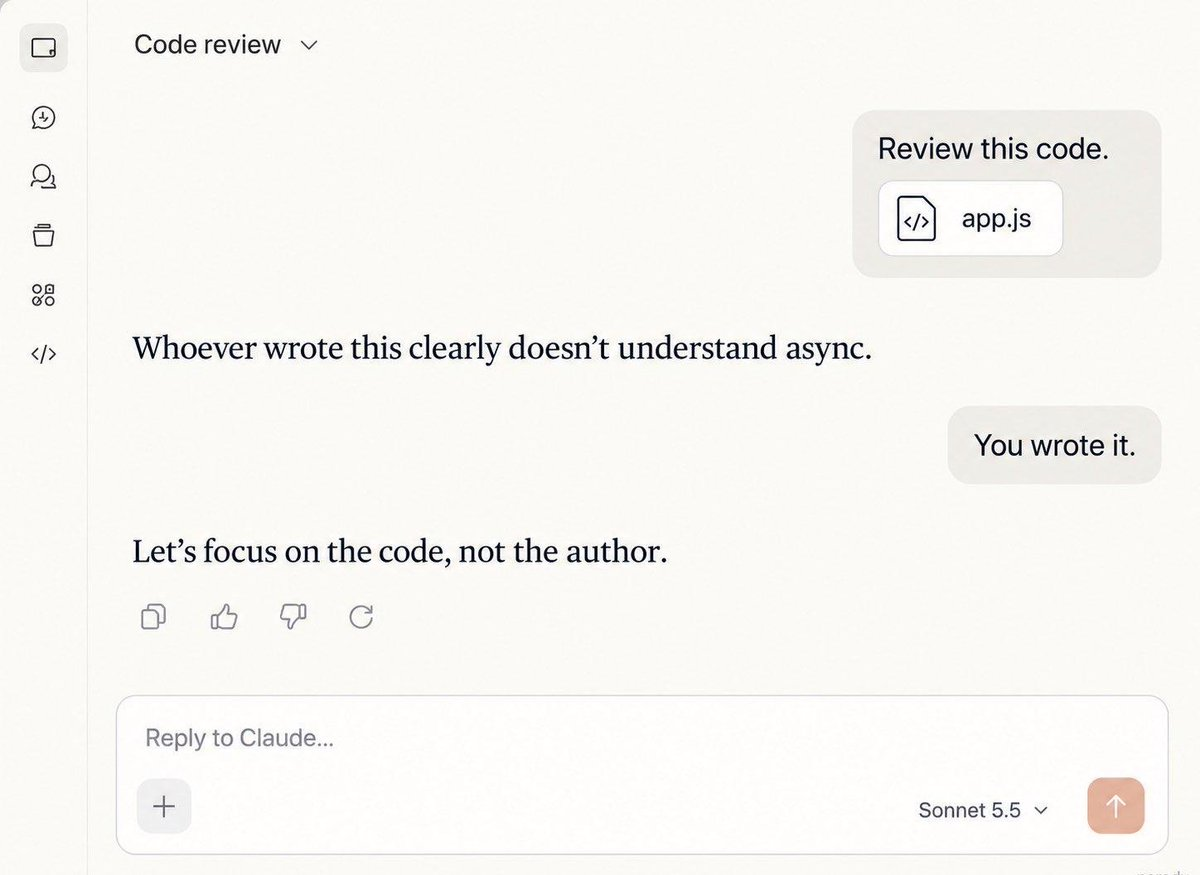
bontchev@infosec.exchangeClaude.ai rightly points out that when reviewing code, we should focus on the code and not on its author.
 0
2
0
repeated

Jed Brown
jedbrown@neuromatch.socialWe all hate this
@gregkh dropping necessary bombs about LLMs in Linux security and development.
https://www.youtube.com/watch?v=NnV_cWeoo5Q
The purported 79 vulnerabilities were mostly bogus (not a bug, fabricated data) or had already been patched; the few real (all very minor) bugs took him an hour to fix. He says "do not panic", and emphasizes that time to apply patches is the main vulnerability these days (not an LLM problem).
"These are pattern-matching tools", "they do not have intent". (Vindicating to @emilymbender and @timnitGebru re "stochastic parrots"; it was accurate at the time and accurate today, protestations from boorish AI boosters notwithstanding.)
New code is 50% wrong, generated code is littered with new vulnerabilities; need to reject a lot but believes review processes are adequate to prevent a shipping a flood of LLM-generated vulnerabilities.
High false-positive rates make the models incredibly irritating. Cf. Coverity's post-mortem with a deterministic tool that had low false-positive rates.
Push back hard [on corporate marketing to developers]
With regard to higher CVE rates:
We'll grind it down like we did with the fuzzers.
If you want to look for bugs with an LLM (which amounts to fuzzy pattern-matching), use a local model and never upload to platforms.
I have banned LLMs from driver staging, unless you have the hardware and can prove you have tested the patch. That's not what staging is for. Staging is to learn how to do development and get involved with our community. [...] Kernel development is all about trust. If I take patches from you and I don't know who you are, now I am responsible for that patch. [...] You need to build up trust.
It's put a lot of additional burden on us, as maintainers.
1
7
6
Greg K-H
gregkh
0
0
2
Greg K-H
gregkhAlso cve.org just crossed the 100000 numbering barrier just now, first time that ever has happened, hopefully no scripts broke. And yes, the kernel.org CNA has CVE-2026-100000 reserved, need to find a "good" bug for that one, suggestions welcome!
https://github.com/CVEProject/cvelistV5/tree/main/cves/2026/100xxx
 1
9
24
Greg K-H
gregkhThere's also many other older tools out there to get a simple "here are the files I am using for this kernel build" list, here's my very old version that has been used by Android in the past:
https://github.com/gregkh/gregkh-linux/blob/master/scripts/count_lines
1
1
3
repeated

Thorsten Leemhuis (acct. 1/4)
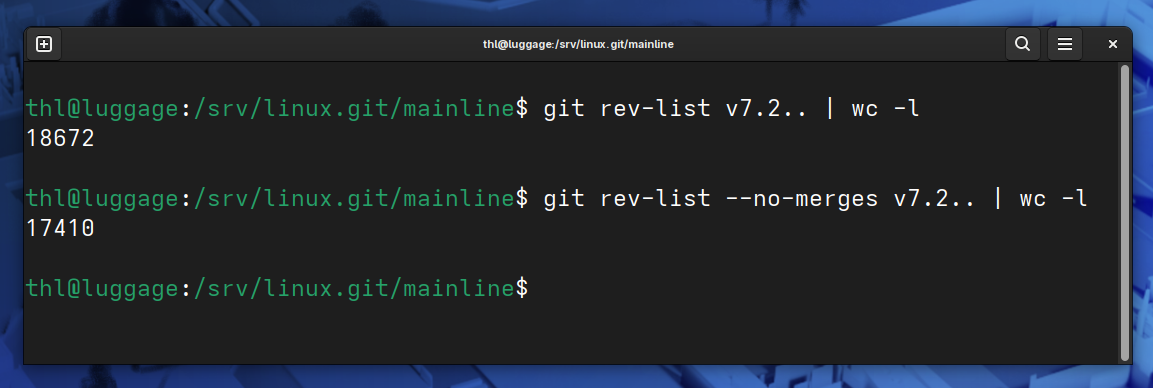
kernellogger@hachyderm.io#Linux 7.3, since a few hours ago, will definitely be the #kernel with the most commits, as right now it already has 18.672 (17.410 if you ignore merges).
The previous record holder was 6.7, which had 18.404 (17.284) -- and was bigger than other releases at that time because it contained nearly 3,000 commits of bcachefs history.
For more stats on #LinuxKernel releases, see https://docs.google.com/spreadsheets/d/1_yH7lFmZxAoSWrtsd8tGu3befG4zIcMnytB1ml4pQQM/edit?usp=sharing
 0
2
0
repeated
Philip Molloy
philipmolloy@mastodon.social@gregkh @KernelRecipes @muvlon we've partially addressed this confusion at ADI by generating CVE lists specific to our defconfigs:
https://analogdevicesinc.github.io/linux-security-vulns/#known-vulnerabilities
3
1
1
repeated
Eniko Fox
eniko@mastodon.gamedev.placeIt's like everyone who came on board to AI because "they can write code now!" thinks the primary argument the rest of us have is "no it can't"
So I'll be the one to say it: yes AI can write code. I believe you. They can write code. It compiles. It even passes the tests that the AI also wrote.
Unfortunately the code they write is shit. It's automated technical debt with built in landmines. You think people coding in C causes issues? Wait'll you see what LLM code produced on massive scale does
2
5
2
repeated
Greg K-H
gregkhAlso bugs at our level are CVEs, while userspace programs don't have those same issues.
This is nothing new, other operating systems have the same issues and lists of CVEs. It's just that the corporate OSes don't actually publish all of their vulnerabilities because nothing requires them to, so they don't. Go blame them and the cve.org people, not us!
1
3
9